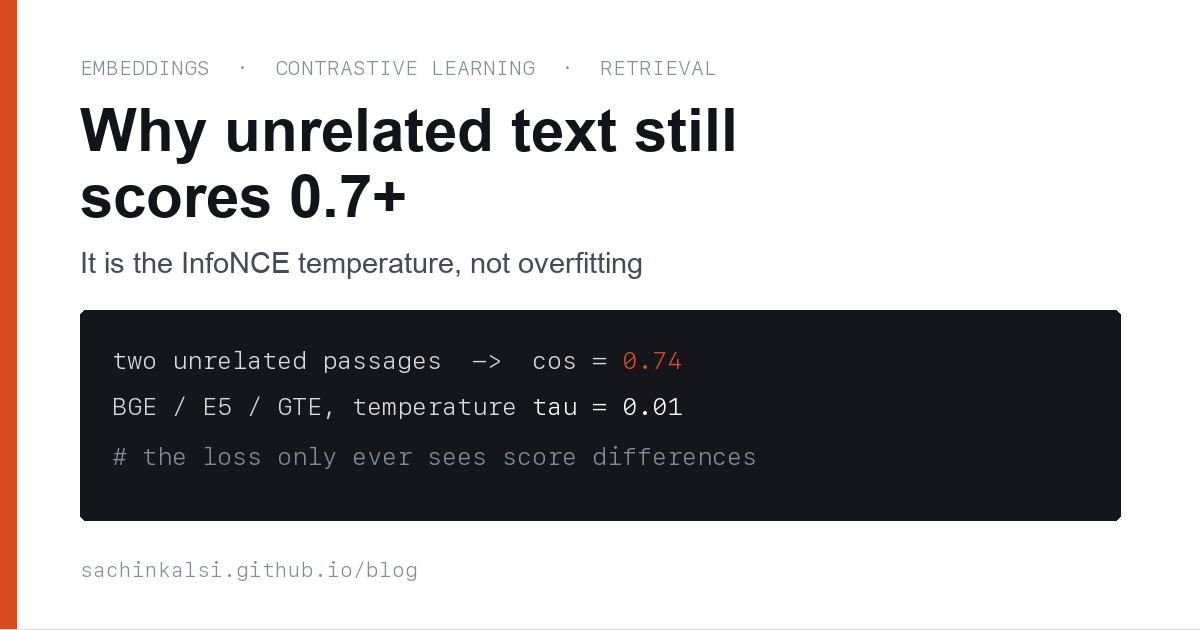
Why Embedding Models Give High Cosine Similarity Scores for Unrelated Text
Unrelated text scores 0.7+ with BGE, E5 and GTE. The reason is the InfoNCE temperature, not overfitting. A...
Building production LLM and NLP systems: retrieval, semantic search, embeddings, and agents that run at scale, not in a notebook.
Unrelated text scores 0.7+ with BGE, E5 and GTE. The reason is the InfoNCE temperature, not overfitting. A...
Lessons from HuggingFace's FineWeb 15T-token recipe: base filtering, why more deduplication can hurt, C4 filters, and how FineWeb-Edu...
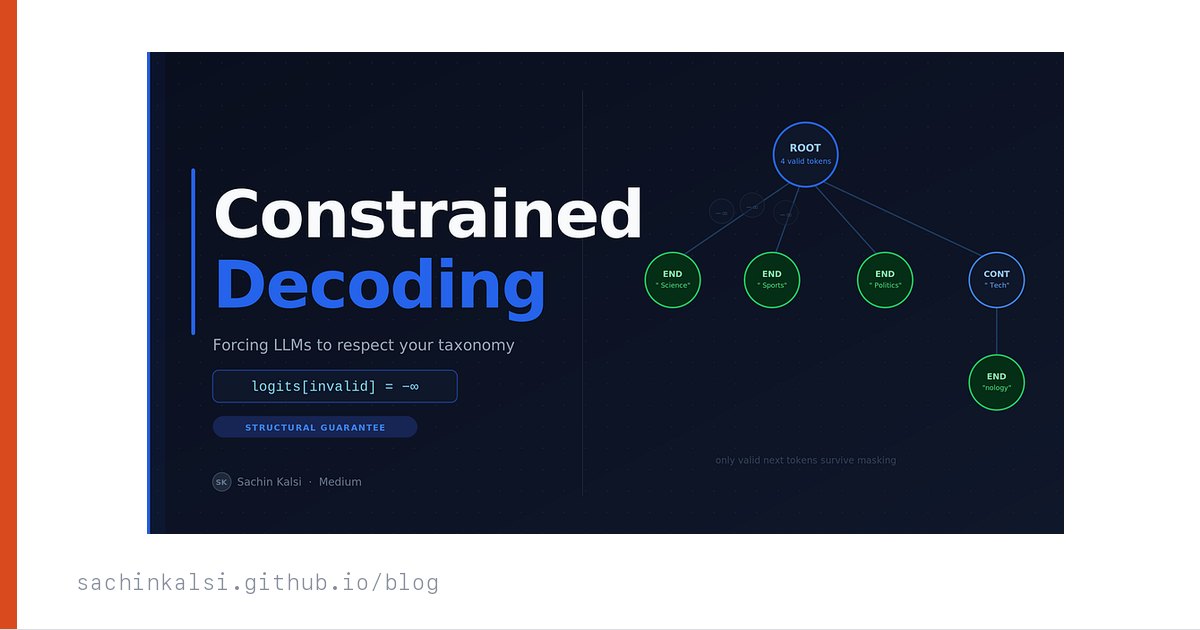
Guarantee an LLM only emits labels from your taxonomy: mask invalid logits to negative infinity and drive the...
A deep dive into the LLaMA 2 architecture, explaining pretraining details, fine-tuning processes, Grouped-Query Attention, and Ghost Attention mechanisms.
A detailed breakdown of Key-Value (KV) caching in transformer models, detailing how it optimizes sequence generation speed by saving key and value tensors.
Learn how PagedAttention, the core technology behind vLLM, manages KV cache memory layout dynamically to reduce fragmentation and scale concurrent LLM serving.